Explore builds
STARTER BUILD / RigAtlas starter

Ryzen 9 9950X + RTX 5080 PC Build.

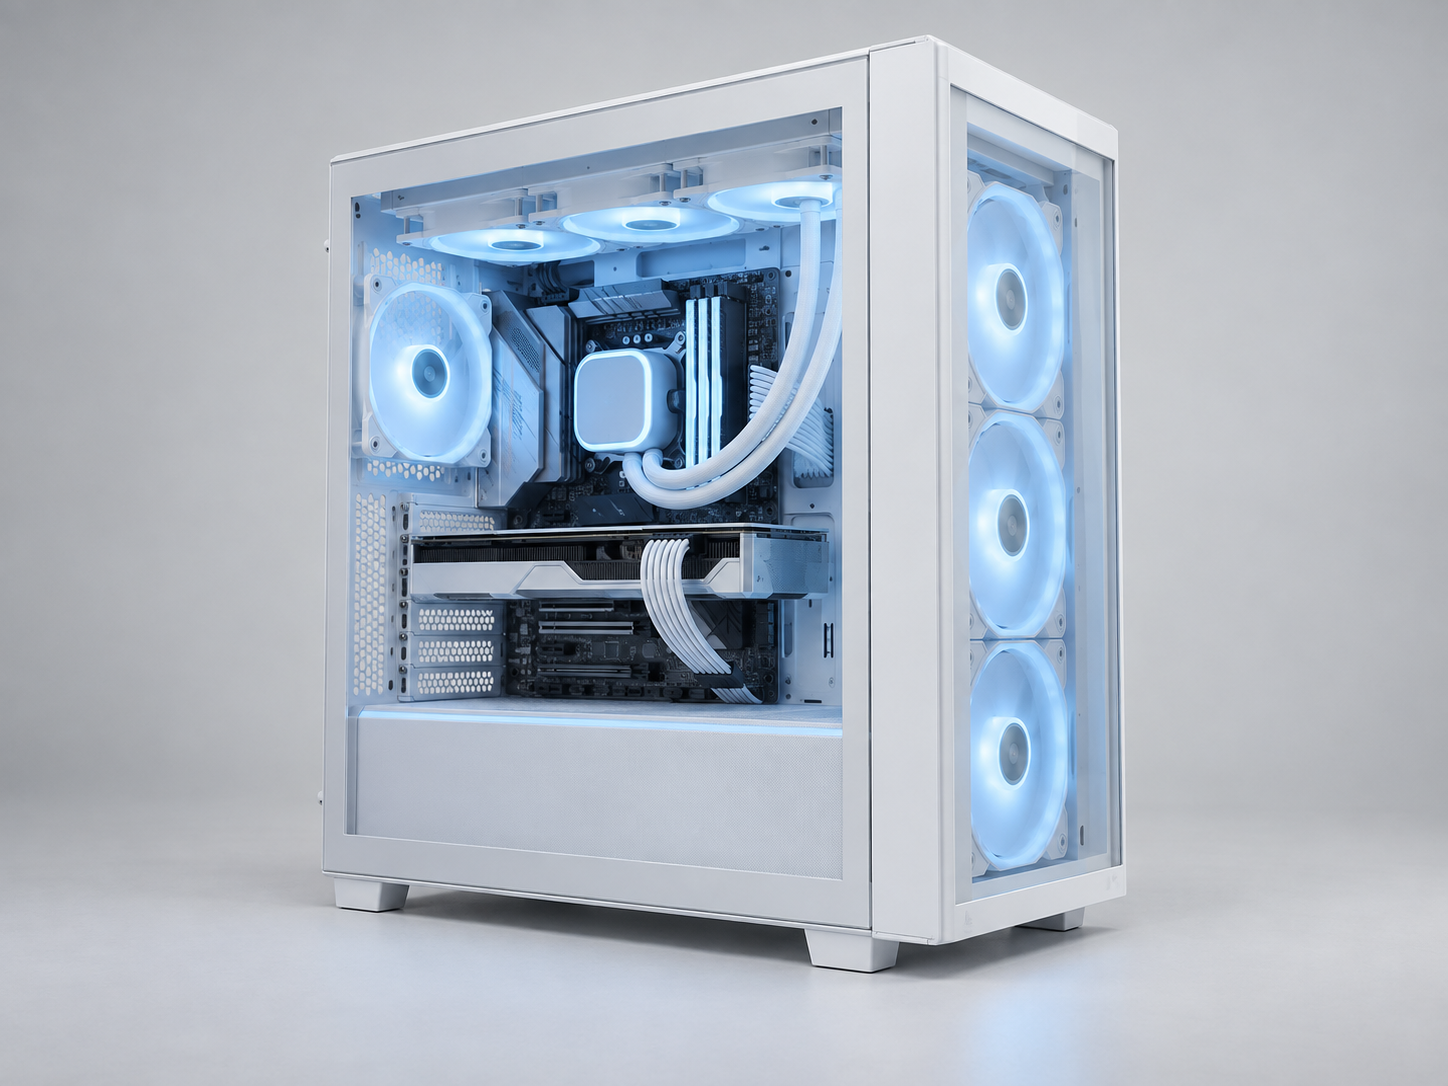
Reference imageImages are for reference only. Refer to the linked store for actual product images.
ABOUT THIS BUILD

A 16-core workstation starting point with 64 GB RAM, a 4 TB SSD and 16 GB GeForce graphics. Choose memory capacity and GPU software support for your actual production applications. This USD budget is an illustrative planning target, not a verified parts total or a retailer quote. Check current local prices, BIOS support and mounting clearances. Images are for reference only. Refer to the linked store for actual product images.

8 componentsBudget in USD
CONFIGURATION

16-core workstation · RTX 5080

8 / 8 core parts
COMPONENTYOUR SELECTIONRECORDED PRICE
Processor
AM5 · DDR5
Checking price…
Not recorded
Motherboard
AM5 · DDR5 · ATX
Checking price…
Not recorded
Graphics card
16 GB GDDR7
Checking price…
Not recorded
Memory
DDR5 · UDIMM
Checking price…
Not recorded
Storage
M.2 2280
Checking price…
Not recorded
Power supply
ATX
Checking price…
Not recorded
CPU cooler
360 mm AIO
Checking price…
Not recorded
Case
Mid-tower
Checking price…
Not recorded
Recorded prices are entered by you in USD. Retailer prices, tax and delivery may differ.
AI & YOUR BUILD

What AI work can this PC handle?

Explore cloud use, local language models and image generation with the parts you selected. Memory estimates are not speed benchmarks.

System memory64 GB
Dedicated graphics memory16 GB
Selected graphics cardGeForce RTX 5080 16G VENTUS 3X OC

Cloud AI

Inference runs on the service’s servers.

A larger local GPU is not required just to chat with a cloud model or request cloud-generated images. Check the service account, availability in your region, internet connection and supported browser or client.

Local editing, 3D work and running several apps still use your PC’s resources. This does not guarantee a service’s response time.

How cloud inference works

Local image generation

Choose the exact model and workflow first.

Check the exact GPU, driver and CUDA support in your chosen application.

Image size, batch size, model components and extra nodes change memory use. CPU offloading can reduce VRAM demand but may be slow. Video generation, training and fine-tuning require separate assessments.

ComfyUI hardware requirementsModel memory and offloading

Local language models

Change the assumptions to explore the memory tradeoff. These are model sizes, not recommendations for a specific model.

Weights may fit; full inference still needs verification.

Theoretical weight storage only: 3.7 GiB · 8B / 4-bit

Actual use is higher: quantization metadata, unquantized tensors, KV cache, compute buffers and the runtime also need memory. Total installed memory is not the same as free memory.

Weight storage scenarios at the selected precision
ParametersWeight lower boundCompared with selected VRAM
3B1.4 GiBWeights only; overhead not included
8B3.7 GiBWeights only; overhead not included
14B6.5 GiBWeights only; overhead not included
32B14.9 GiBWeights only; overhead not included
70B32.6 GiBNot enough for weights alone
  • Check the exact GPU, driver and CUDA support in your chosen application.
  • Longer context increases KV-cache demand. A weights-only fit does not establish whether your selected context or concurrent requests will fit.
  • Check CPU instruction support, the exact OS version, drivers and available SSD space for model downloads. LM Studio on Windows x64 requires AVX2; this catalog does not verify instruction sets.
Method, limits and how to verify

Weight lower bound = total parameters × bits ÷ 8. B means one billion parameters; GiB means 2³⁰ bytes. All parameters are counted, including inactive experts in a mixture-of-experts model. Nominal catalog RAM and VRAM capacities are used as GiB for this planning comparison.

Shared system memory is not added to dedicated VRAM. RAM kit capacity is counted once. Already-owned parts still count as installed hardware. No throughput or “smooth performance” claim is made.

After assembly, use the actual model file and context setting with the runtime’s resource estimator, then measure response speed and memory use in your workload.

LM Studio resource estimation

Weight estimates · Context and memory · GPU runtime support · Application requirements

Selected GPU manufacturer specifications · 2026-09-10

AI documentation checked: 2026-09-19
THE CHOICES BEHIND THIS PARTS LIST

Who this build is for

A 16-core Ryzen 9 9950X parts list with 64 GB system memory and an RTX 5080 for evaluating substantial CPU and GPU creative workloads.

Why these components are together

The CPU's core count is a capacity choice for workloads that can use it; it is not proof that every editor or export is faster. The 16 GB GPU has its own software and memory requirements.

The 4 TB 990 PRO expands local storage while the 64 GB DDR5 kit expands working memory. Keep project size, caches and a separate backup plan visible in the decision.

The X870 board, 360 mm NAUTILUS and H7 Flow create a full-size liquid-cooled installation whose exact mounting and fan control should be planned before assembly.

Tradeoffs and checks before ordering

  • Check the renderer or editor's supported acceleration backend and driver requirements.
  • Long-running workloads make stable memory settings and sustained cooling relevant; a short boot test cannot establish either.
  • The motherboard and PSU need to suit the full system, including any later drives or cards.

What to change first

Use a representative project to identify whether CPU time, GPU work, RAM or storage is limiting you. Avoid moving to a more expensive CPU if the actual task is limited by GPU memory or project storage.

This is an editorial parts-list explanation. The planning target is not a current retailer total, and this configuration has not been benchmarked by RigAtlas.

Component specification sources