Explore builds
STARTER BUILD / RigAtlas starter

Core i5-12400F + RX 7600 PC Build.

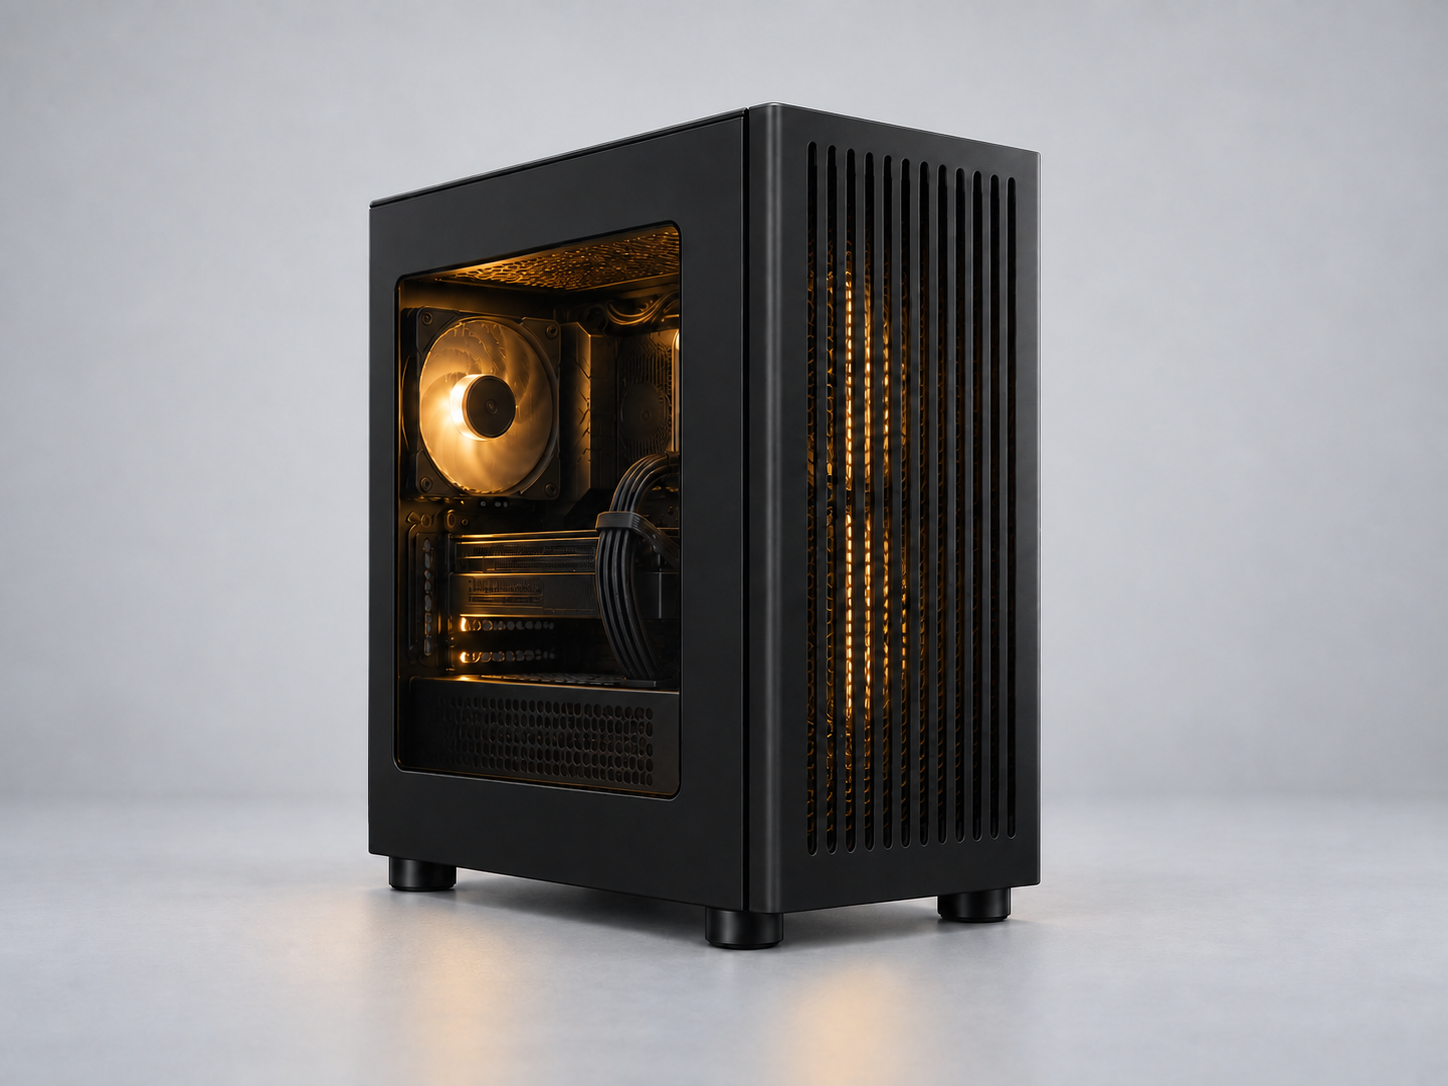
Reference imageImages are for reference only. Refer to the linked store for actual product images.
ABOUT THIS BUILD

A micro-ATX starting point built around an LGA1700 processor and DDR4 memory. The compact enclosure needs its own clearance checks. Images are for reference only. Refer to the linked store for actual product images.

8 componentsBudget in USD
CONFIGURATION

Compact Intel

8 / 8 core parts
COMPONENTYOUR SELECTIONRECORDED PRICE
Processor
LGA1700 · DDR4/DDR5
Checking price…
Not recorded
Motherboard
LGA1700 · DDR4 · micro-ATX
Checking price…
Not recorded
Graphics card
8 GB GDDR6
Checking price…
Not recorded
Memory
DDR4 · UDIMM
Checking price…
Not recorded
Storage
M.2
Checking price…
Not recorded
Power supply
ATX
Checking price…
Not recorded
CPU cooler
Four-heatpipe tower air cooler
Checking price…
Not recorded
Case
Mini-tower
Checking price…
Not recorded
Recorded prices are entered by you in USD. Retailer prices, tax and delivery may differ.
AI & YOUR BUILD

What AI work can this PC handle?

Explore cloud use, local language models and image generation with the parts you selected. Memory estimates are not speed benchmarks.

System memory32 GB
Dedicated graphics memory8 GB
Selected graphics cardPULSE Radeon RX 7600 8GB

Cloud AI

Inference runs on the service’s servers.

A larger local GPU is not required just to chat with a cloud model or request cloud-generated images. Check the service account, availability in your region, internet connection and supported browser or client.

Local editing, 3D work and running several apps still use your PC’s resources. This does not guarantee a service’s response time.

How cloud inference works

Local image generation

Choose the exact model and workflow first.

AMD support varies by GPU, operating system and runtime. Check that application’s current ROCm or Vulkan matrix.

Image size, batch size, model components and extra nodes change memory use. CPU offloading can reduce VRAM demand but may be slow. Video generation, training and fine-tuning require separate assessments.

ComfyUI hardware requirementsModel memory and offloading

Local language models

Change the assumptions to explore the memory tradeoff. These are model sizes, not recommendations for a specific model.

Weights may fit; full inference still needs verification.

Theoretical weight storage only: 3.7 GiB · 8B / 4-bit

Actual use is higher: quantization metadata, unquantized tensors, KV cache, compute buffers and the runtime also need memory. Total installed memory is not the same as free memory.

Weight storage scenarios at the selected precision
ParametersWeight lower boundCompared with selected VRAM
3B1.4 GiBWeights only; overhead not included
8B3.7 GiBWeights only; overhead not included
14B6.5 GiBWeights only; overhead not included
32B14.9 GiBNot enough for weights alone
70B32.6 GiBNot enough for weights alone
  • AMD support varies by GPU, operating system and runtime. Check that application’s current ROCm or Vulkan matrix.
  • Longer context increases KV-cache demand. A weights-only fit does not establish whether your selected context or concurrent requests will fit.
  • Check CPU instruction support, the exact OS version, drivers and available SSD space for model downloads. LM Studio on Windows x64 requires AVX2; this catalog does not verify instruction sets.
Method, limits and how to verify

Weight lower bound = total parameters × bits ÷ 8. B means one billion parameters; GiB means 2³⁰ bytes. All parameters are counted, including inactive experts in a mixture-of-experts model. Nominal catalog RAM and VRAM capacities are used as GiB for this planning comparison.

Shared system memory is not added to dedicated VRAM. RAM kit capacity is counted once. Already-owned parts still count as installed hardware. No throughput or “smooth performance” claim is made.

After assembly, use the actual model file and context setting with the runtime’s resource estimator, then measure response speed and memory use in your workload.

LM Studio resource estimation

Weight estimates · Context and memory · GPU runtime support · Application requirements

Selected GPU manufacturer specifications · 2026-09-09

AI documentation checked: 2026-09-19
THE CHOICES BEHIND THIS PARTS LIST

Who this build is for

A micro-ATX LGA1700 configuration with an RX 7600, useful for comparing a compact DDR4 build and potentially reused older-platform parts.

Why these components are together

The Core i5-12400F needs a discrete graphics card for output. The PRIME B660M-A D4 requires DDR4, so the 32 GB LPX kit is part of that platform choice.

The RX 7600 8 GB is an exact graphics selection rather than a guarantee for all games at a particular resolution. The 1 TB 980 PRO provides one initial storage device.

The AK400 and Q300L use air cooling in a smaller enclosure. Check the actual board, GPU, PSU and cable layout together before assuming the listed limits settle the fit.

Tradeoffs and checks before ordering

  • An LGA1851 CPU or DDR5 kit cannot be substituted while keeping this board.
  • Some storage-length details need manual confirmation for an exact board slot.
  • Case airflow and noise require testing after assembly; size alone does not predict them.

What to change first

When starting from scratch, compare the total with a newer platform. If reusing the board or RAM, include those savings, then verify whether a targeted GPU or storage upgrade actually meets the intended task.

This is an editorial parts-list explanation. The planning target is not a current retailer total, and this configuration has not been benchmarked by RigAtlas.

Component specification sources